Aivora
Choosing the right ai inference server manufacturer is now a strategic infrastructure decision. IDC’s Worldwide AI and Generative AI Spending Guide projects global investment will exceed $630 billion by 2028. That growth reflects a practical shift from experimental models to always-on production services. A server may look impressive in a showroom, yet fail under sustained workloads. Buyers must examine accelerator compatibility, memory bandwidth, network throughput, power draw, cooling design, and warranty coverage. Small details matter. A delayed replacement fan can interrupt a customer-facing application.
Experience should guide the evaluation, but measurable evidence should lead it. MLCommons’ MLPerf Inference benchmarks provide a useful comparison of latency, throughput, and energy efficiency across supported systems. These results do not represent every deployment. Still, they offer a stronger starting point than marketing claims alone. The Uptime Institute’s data center research also continues to emphasize power availability, thermal management, and operational resilience. A reliable manufacturer should explain how its systems perform inside real racks, not only in controlled laboratories.
This guide examines how to compare vendors with greater confidence. It considers architecture, deployment support, software ecosystems, security practices, lifecycle planning, and total cost of ownership. Vendor references deserve close attention. Ask for evidence from workloads resembling yours, including response-time targets and daily request volumes. No checklist is perfect. A manufacturer with the fastest benchmark score may not provide the best field support. The right decision balances verified performance, engineering transparency, service responsiveness, and future upgrade paths. That balance can protect both budgets and production reliability.
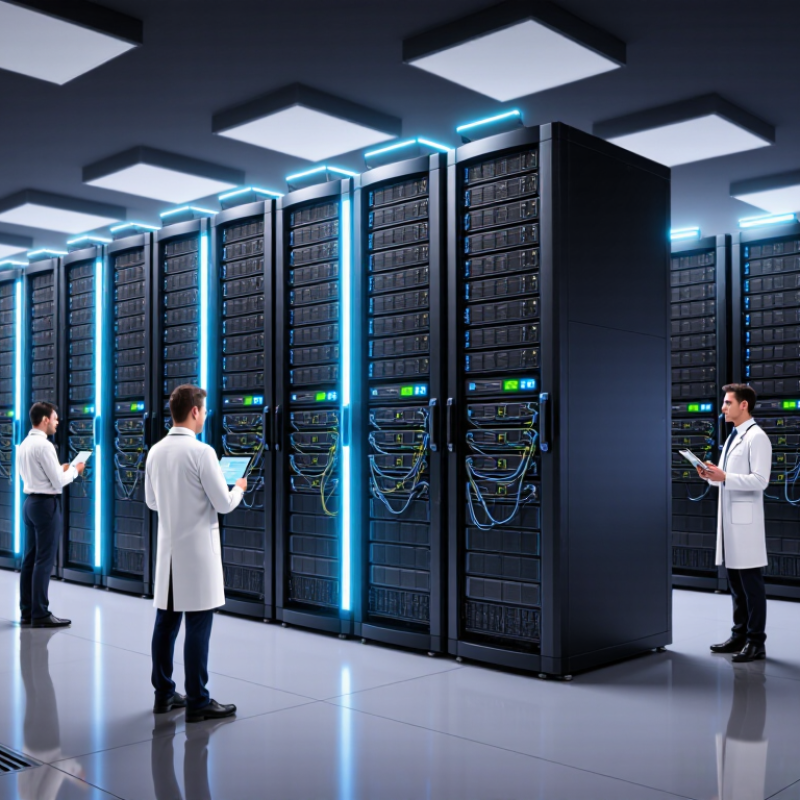
An AI inference server manufacturer does more than assemble processors, memory, and storage. Its role begins with matching hardware to real workloads. Image recognition, language generation, and industrial inspection create different latency and memory demands. A responsible manufacturer designs the complete platform, including cooling, power delivery, firmware, and network interfaces. Small details matter. A blocked air vent can reduce performance within minutes.
In practical deployments, manufacturers should provide workload-based benchmarks, not only peak processing numbers. Ask how tests measure response time, throughput, power use, and performance stability. Clear documentation also shows technical maturity. It should explain installation, driver compatibility, remote management, and maintenance procedures. Experienced teams will discuss trade-offs honestly. More accelerators may increase capacity, but they can also raise heat, noise, and operating costs.
Reliability depends on the years after delivery. Check spare-part availability, firmware update policies, diagnostic tools, and support response times. Request evidence from comparable environments, while verifying the testing conditions carefully. A polished benchmark can hide difficult integration work. I have learned that simple deployment plans often become complicated in production. That is not always a failure, but it deserves attention. The strongest manufacturer accepts these imperfections, records them, and improves the design through measurable feedback.
Choosing an AI inference server begins with the workload, not the product brochure. Measure model size, request volume, response latency, and expected growth. A vision system processing warehouse images may need high throughput, while a voice assistant needs consistent low latency. These goals require different processor, accelerator, and memory configurations.
During deployment reviews, I check accelerator memory before counting compute cores. Large models can fail when memory is slightly undersized. Fast interconnects also matter when several accelerators share one workload. Review cooling capacity, power limits, rack space, and replacement procedures. Small details matter. A blocked airflow path can reduce performance within minutes.
Software compatibility deserves equal attention. The server should support the required operating system, inference runtime, container tools, and orchestration environment. Look for dynamic batching, model quantization, monitoring, access control, and reliable update methods. Test real models with realistic traffic, not only laboratory samples. A perfect benchmark is rare. I once underestimated preprocessing time, and the accelerator stayed idle while the CPU handled image conversion. That mistake changed our evaluation method. Ask for transparent performance data, documented service procedures, security maintenance, and measurable response targets. Independent testing adds confidence, but results still depend on configuration and workload.
Comparing Performance, Scalability, and Energy Efficiency
Choosing an inference server requires more than reading peak throughput figures. Ask manufacturers for results using your model, input length, batch size, and target latency. Measure tokens per second, p95 latency, and requests completed during sustained workloads. Short demonstrations can hide thermal throttling.
I have found memory capacity equally important. A server may process one model quickly, yet fail when several models share the same accelerator. Check support for model isolation, dynamic batching, quantization, and fast model loading. Test scaling across multiple servers, not only inside one rack. Network delays matter.
Energy efficiency deserves direct measurement. Request performance-per-watt data from realistic workloads, including cooling and host-system power. Review power limits, airflow requirements, telemetry, and recovery behavior after overloads. A compact server can still consume excessive electricity when utilization remains low. Look beyond attractive specifications.
I once trusted a synthetic benchmark too much. The production results were weaker. That mistake changed my evaluation process. I now request a trial with anonymized workload traces, clear acceptance criteria, and written support commitments. Examine firmware update practices, component availability, warranty response times, and technician expertise. Reliable vendors should explain limitations openly, because every platform involves trade-offs.
Evaluating Reliability, Security, and Technical Support
Reliability Reliability starts with evidence, not impressive specifications. The 2024 Global Data Center Survey found that 54% of respondents reported recent outages costing more than $100,000. Ask manufacturers for failure-rate data, burn-in procedures, spare-part policies, and repair timelines. Test thermal stability under sustained inference workloads, not only short benchmark runs. A quiet rack at noon may behave differently overnight.
Security Security requires controls across hardware, firmware, and deployment tools. The 2024 Cost of a Data Breach Report placed the global average breach cost at $4.88 million. Request secure boot, signed firmware, vulnerability disclosure procedures, and clear patch commitments. Also inspect access logging and administrator separation. Security claims without audit evidence remain marketing language. That is uncomfortable, but important.
Technical Support Technical support becomes visible during failure. Require regional response times, escalation paths, remote diagnostics, and engineers familiar with model-serving software. Define service-level targets in writing, including weekend coverage and replacement logistics. Ask for anonymized incident examples. A manufacturer that cannot explain a difficult recovery may struggle with yours. I would still run a pilot, because documentation can hide practical weaknesses. Measure ticket quality, firmware updates, recovery time, and performance drift for at least thirty days.
How to Choose the Best AI Inference Server Manufacturer?
Selecting the Manufacturer That Best Fits Your Deployment Needs
The best manufacturer is not always the one with the highest benchmark score. Your deployment environment matters more. A production server may run beside factory equipment, inside a quiet office, or in a crowded data center. Each location creates different demands for noise, cooling, rack space, and power. Define your inference workload carefully. Measure model size, response latency, daily request volume, and expected growth. Confirm support for your preferred accelerators, networking standards, operating systems, and container tools. Compatibility should be tested, not assumed.
Tips: Request a live workload demonstration. Ask for thermal readings, power consumption, service response times, and replacement procedures. Review warranty terms and firmware update policies. Speak with engineers who have deployed similar systems. Their practical experience often reveals problems hidden by product sheets. Check whether spare components are available in your region. Delays can cost more than the original hardware.
A reliable manufacturer should explain trade-offs clearly. It should provide validation reports, documented performance methods, and transparent limitations. Security controls also deserve attention, including secure boot, access management, and update integrity. I once focused too heavily on peak throughput and underestimated maintenance access. That mistake changed the evaluation process. No checklist is perfect. Recheck your assumptions with a pilot installation. Choose the supplier that can support your complete operating reality, not merely your planned purchase.
Selecting the manufacturer that best fits your deployment needs
The chart presents a practical weighting model for comparing AI inference server solutions across three common deployment environments. Edge deployments typically prioritize power efficiency and latency, private data centers place greater emphasis on security and memory capacity, while large-scale cloud deployments focus on throughput, scalability, and total cost efficiency. Use these priorities as a starting point and adjust them to match your workload, model size, traffic pattern, and service-level objectives.
It designs the full platform, not just the processor package. This includes accelerators, memory, cooling, power delivery, firmware, and networking. Small details matter.
Start with model size, request volume, latency targets, and expected growth. Image processing may need high throughput. Voice applications often require steady, low latency.
Check accelerator memory before counting compute cores. Large models can fail when memory is slightly undersized. Also review interconnect speed, rack space, airflow, and replacement procedures.
Verify the operating system, inference runtime, container tools, and orchestration environment. Ask about quantization, dynamic batching, monitoring, access control, and update methods.
Test your model with realistic traffic, input lengths, and batch sizes. Measure throughput, p95 latency, power use, and sustained stability. Short demonstrations can hide thermal throttling.
Request performance-per-watt results from complete workloads. Include cooling and host-system power. A compact server may still waste electricity when utilization stays low.
Request spare-part policies, firmware support, diagnostic tools, and response targets. Comparable deployment evidence helps, but verify the testing conditions carefully. Polished benchmarks can hide integration work.
I once underestimated preprocessing time, leaving the accelerator idle while the CPU converted images. Another synthetic benchmark looked impressive but performed poorly later. Trial workloads reveal uncomfortable gaps.
Choosing the right ai inference server manufacturer is essential for building a reliable and efficient AI deployment environment. The evaluation should begin with a clear understanding of the manufacturer’s role, including its ability to provide compatible hardware, optimized software, system integration, and long-term product support. Organizations should then define their core requirements, such as processor and accelerator capacity, memory, storage, networking, operating system compatibility, and support for their intended AI workloads.
A thorough comparison should consider inference speed, scalability, energy efficiency, system reliability, data protection, and technical assistance. A strong manufacturer should offer stable performance under continuous workloads, flexible expansion options, effective security measures, clear maintenance policies, and responsive support. By matching these capabilities with workload demands, budget limitations, deployment scale, and future growth plans, organizations can select a manufacturer that delivers dependable performance and sustainable value throughout the server’s lifecycle.